
Measured on a Mac
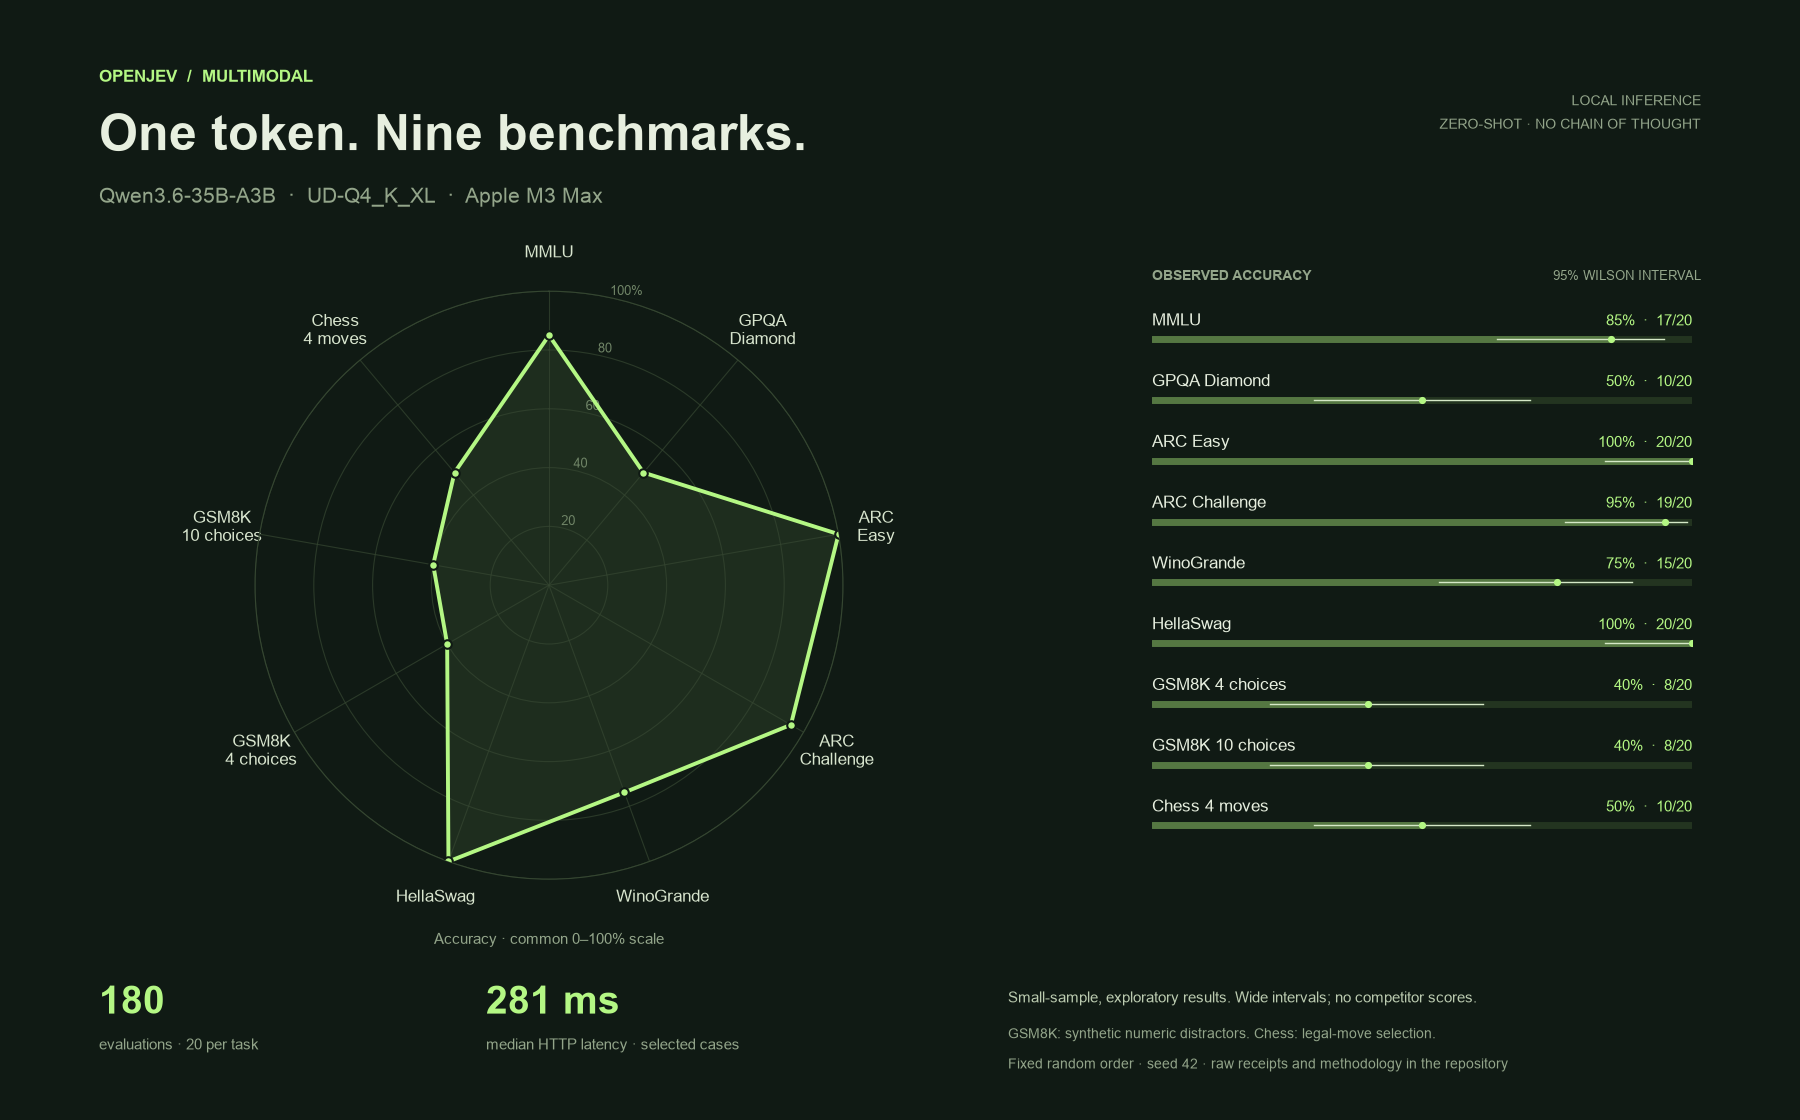
Only our OpenJev Multimodal API is plotted. No Jev, Terra or third-party model scores are copied into this chart.
| Task | Correct | Accuracy | 95% Wilson interval | Median HTTP latency |
|---|---|---|---|---|
| MMLU | 17/20 | 85% | 64.0–94.8% | 228 ms |
| GPQA Diamond | 10/20 | 50% | 29.9–70.1% | 294 ms |
| ARC Easy | 20/20 | 100% | 83.9–100.0% | 242 ms |
| ARC Challenge | 19/20 | 95% | 76.4–99.1% | 245 ms |
| WinoGrande | 15/20 | 75% | 53.1–88.8% | 210 ms |
| HellaSwag | 20/20 | 100% | 83.9–100.0% | 362 ms |
| GSM8K · 4 choices | 8/20 | 40% | 21.9–61.3% | 306 ms |
| GSM8K · 10 choices | 8/20 | 40% | 21.9–61.3% | 340 ms |
| Chess · 4 moves | 10/20 | 50% | 29.9–70.1% | 554 ms |
Median HTTP latency over the selected 180 cases: 281 ms. This subset is exploratory, with wide uncertainty intervals. A 20/20 observation does not establish 100% population accuracy. Radar area is not an aggregate score.
Conditions
- Model: Qwen3.6-35B-A3B, UD-Q4_K_XL weights plus matching F16 projector.
- Hardware: Apple M3 Max, 40-core GPU, 128 GB unified memory.
- Backend: llama.cpp b9670 /
02810c7aa, Metal, one slot, 8,192 context. - Protocol: zero-shot, one output token per question, no generated reasoning, option order shuffled.
- Selection: first 20 cases in each task's original seed-42 random sample order, with no correctness-based filtering.
- Timing: wall-clock HTTP request/response on an already loaded model. Includes API preparation, backend work and cache effects. Downloads/model loading excluded. Desktop activity was not isolated.
An initial larger sequential run was interrupted to limit local load. All 886 completed decisions remain archived. The chart uses 180 of those existing observations; it did not trigger another inference run.
Tasks and interpretation
MMLU samples the combined test split, not a subject-macro average. GPQA Diamond uses the authors' public password-protected archive; prompts and answer texts are not republished. ARC uses test splits; WinoGrande and HellaSwag use labeled validation splits.
GSM8K is adapted to multiple choice with the gold number and reproducible synthetic numeric distractors. It is not standard free-response GSM8K. Chess is a synthetic position/legality task: one legal UCI move among three illegal moves, validated with python-chess. It does not measure Elo or best-move search.
These nine axes evaluate text judgments. The separate image demo proves the vision path runs; it is not a broad visual-accuracy benchmark.
Reproduce with bounded load
# One model, one request at a time.
uv run openjev serve --profile quality --threads 4

# In a second terminal: a NEW small sample, with rest between calls.
uv run --group bench python scripts/benchmark.py \
  --samples 20 --cooldown 0.25 --output benchmarks/local

# Replay exactly the published sample IDs and pinned dataset sources.
uv run --group bench python scripts/benchmark.py \
  --replay-report benchmarks/quality/summary.json \
  --cooldown 0.25 --output benchmarks/replay

# Re-render the published chart without any inference.
uv run --group bench python scripts/render_benchmark.py
Summary + selected IDs · All completed per-question receipts · Run manifest and dataset revisions · SVG image.